1Install
One command into ~/.local/bin; no root.
$ curl -fsSL https://autooptm.com/install.sh | sh
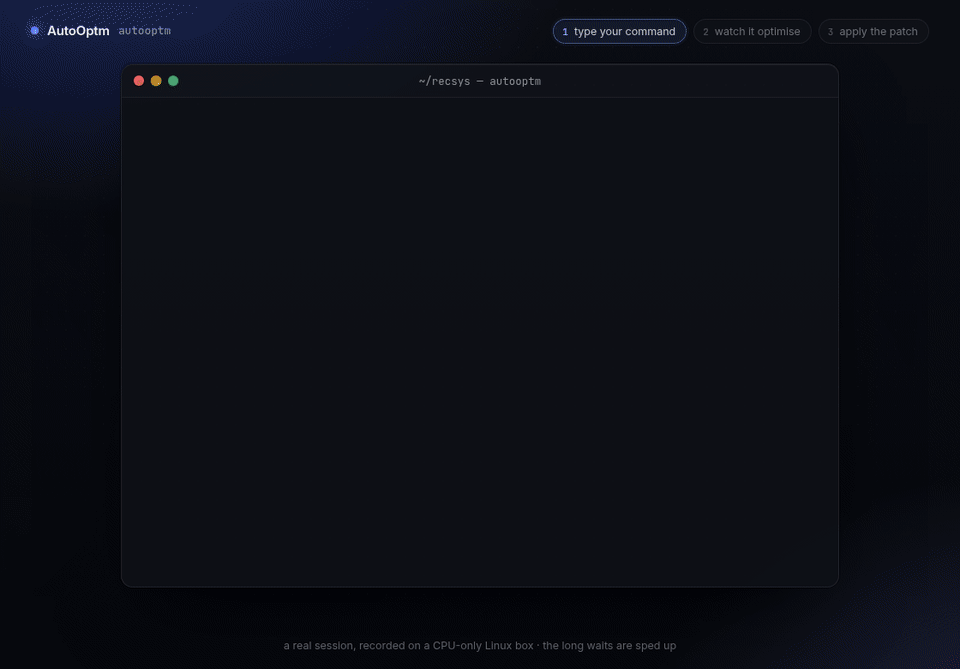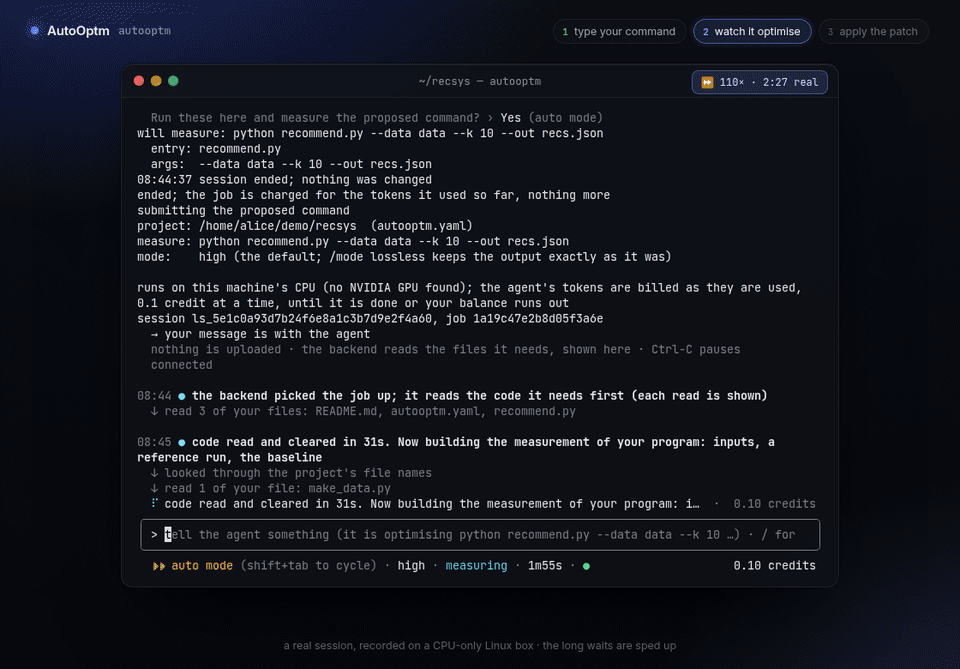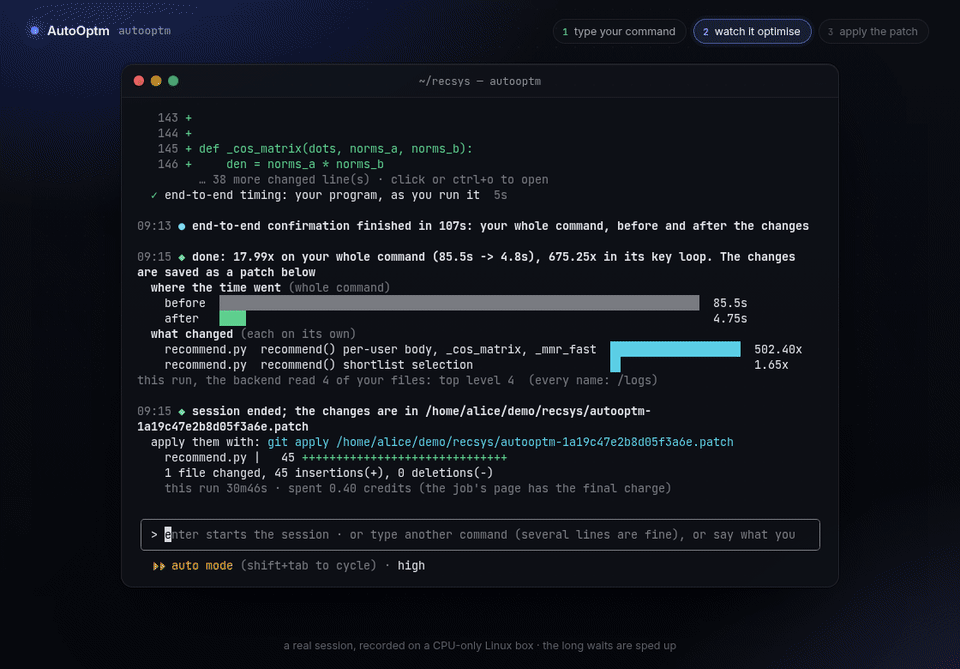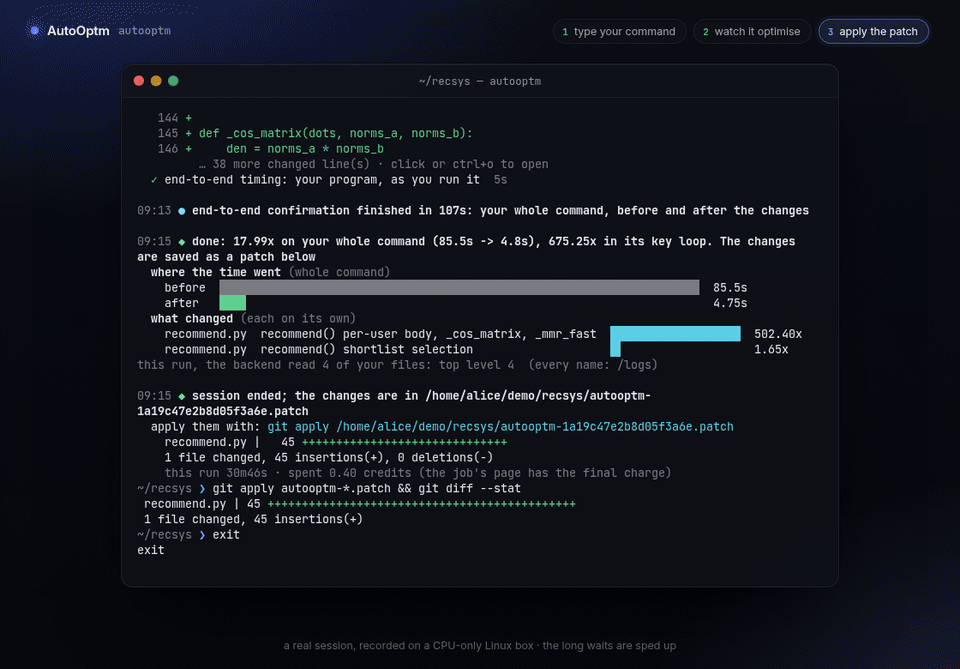
Run autooptm in your project: the agent measures, changes and verifies on your own machine, and hands you a patch.
$ curl -fsSL https://autooptm.com/install.sh | sh
$ cd your-project && autooptm
Linux / macOS · How it works → · Gift rules →
No suitable GPU, or rather leave it to us? Paste a repo or upload a zip; the estimate is free:
Measured on public repositories · end to end · output verified
Same command, timed end to end, output checked. Results vary with the GPU and the inputs.
01 Getting started
One command into ~/.local/bin; no root.
$ curl -fsSL https://autooptm.com/install.sh | shIn the environment your program runs in (conda / venv). The first time, you approve this machine in the browser.
$ cd your-project && autooptmThe line you normally run it with. The agent optimises, and you end with a patch.
> python train.py --epochs 1
$ git apply autooptm-*.patch
Or not on your machine at all: upload the code, or autooptm run --cloud ., and it runs on our GPUs; the estimate is free. Full docs →
$ git apply autooptm.patch
$ python your/entry.py …
A standard diff with no dependency on our service. Your code runs exactly as it did before.
Your command and your inputs, sampled repeatedly before and after, with the median reported.
03 Why us
| AutoOptm | ClaudeOpenAICodexQwenDeepSeekPrompting an LLM yourself | Hiring an engineering team | |
|---|---|---|---|
| Speedup | 2.48×median · 50+ projects measured | ~1.4×typical | Variesdepends on who and how long |
| Cost | $3.5a third of runs cost this or less · median $4.60 · free if no speedup | $9+coding plan + rented GPU · ~$19 on API pricing | $4k–8k~$100/hour × 1–2 weeks |
| Time to result | 1–3 h2.3 h median · unattended | 1–2 hyour own time, prompting and watching | 1–2 wkscheduling, meetings, hand-off |
| Your time | Submit and walk away | All of it | Meetings, Q&A, review |
| Output changes | Never; out-of-tolerance changes revert | Unchecked | Up to the engineer |
| Proof | Frozen harness, median of repeated runs | Build it yourself | Self-reported |
| No speedup | Not charged | Tokens still billed | Hours still billed |
04 Integrations
$ curl -fsSL https://autooptm.com/install.sh | sh
$ cd your-project && autooptm
Your code runs only on your machine; the agent works remotely. No machine charge; tokens at 10% of list, billed as used.
$ curl -fsSL https://autooptm.com/install.sh | sh
$ autooptm run --cloud . --entrypoint infer.py
$ autooptm unlock <jobId>
$ git apply autooptm.patch
A free estimate first, then it runs to the end and prints the speedup and price. You review the file list before anything uploads.
$ curl -fsSL https://autooptm.com/install.sh | sh
$ autooptm install-skill
Then just tell Claude Code: "optimise this repo with AutoOptm".
05 Who this is for
Halve the step time; run twice the experiments on the same budget.
Twice as fast on one GPU is a second GPU for free.
The same 4090 serves twice the requests at half the unit cost.
They train three models a night; you train six.
06 Code security
One isolated sandbox per run, destroyed after; our dispatcher never runs your code.
No tokens, no GitHub App. Paste a public URL or upload a .zip.
Reports and patches need sign-in to download; your code and data never train models.
The full terms are in the privacy policy.
07 Pricing
No speedup, or the failure is ours: the deposit comes back. Refund details →
New accounts get 50 credits: ready to spend on your own machine in the TUI, and on our GPUs too while you subscribe. Invite a friend: when they make their first purchase you get 10 credits, and once they have paid $28 you each get 20. Gift and referral rules →
$0.50–$5000. Card or WeChat Pay; WeChat Pay requires scanning a QR code on desktop.
Install it and run autooptm in your project; the 50 credits you get at sign-up are ready to spend. Rather not run it here? Hand the code to our GPUs; the estimate is free.